A small model is a task-fit decision
Anthropic introduced Claude Haiku 5.5 on October 7 and positioned it as the fastest and most efficient model in its 5.5 family for high-volume, cost-sensitive work. Those are vendor descriptions, not evidence that a given business process will be cheaper or faster after review and exception handling are counted.
Start with a repetitive step where a human can quickly spot a mistake: classifying incoming requests, extracting a few known fields, or routing a document to the right queue. Avoid beginning with a high-consequence decision or an open-ended assistant. The first test should answer whether this model can perform one bounded task reliably enough to reduce work without hiding important edge cases.
Build a representative test set
Take a sample that includes ordinary cases, messy inputs, missing fields, and cases that should be escalated. Remove personal or confidential values when possible, but preserve the variation that makes the workflow difficult. Write down the expected answer and the evidence a reviewer would use to decide whether the output is acceptable.
Score both the model’s classification and the labor around it. Count corrections, escalations, retries, and time spent checking the result. A short answer may still require careful review; a low token rate does not measure that cost. Avoid extrapolating from a handful of successful examples to a monthly savings claim.
Compare the fallback path
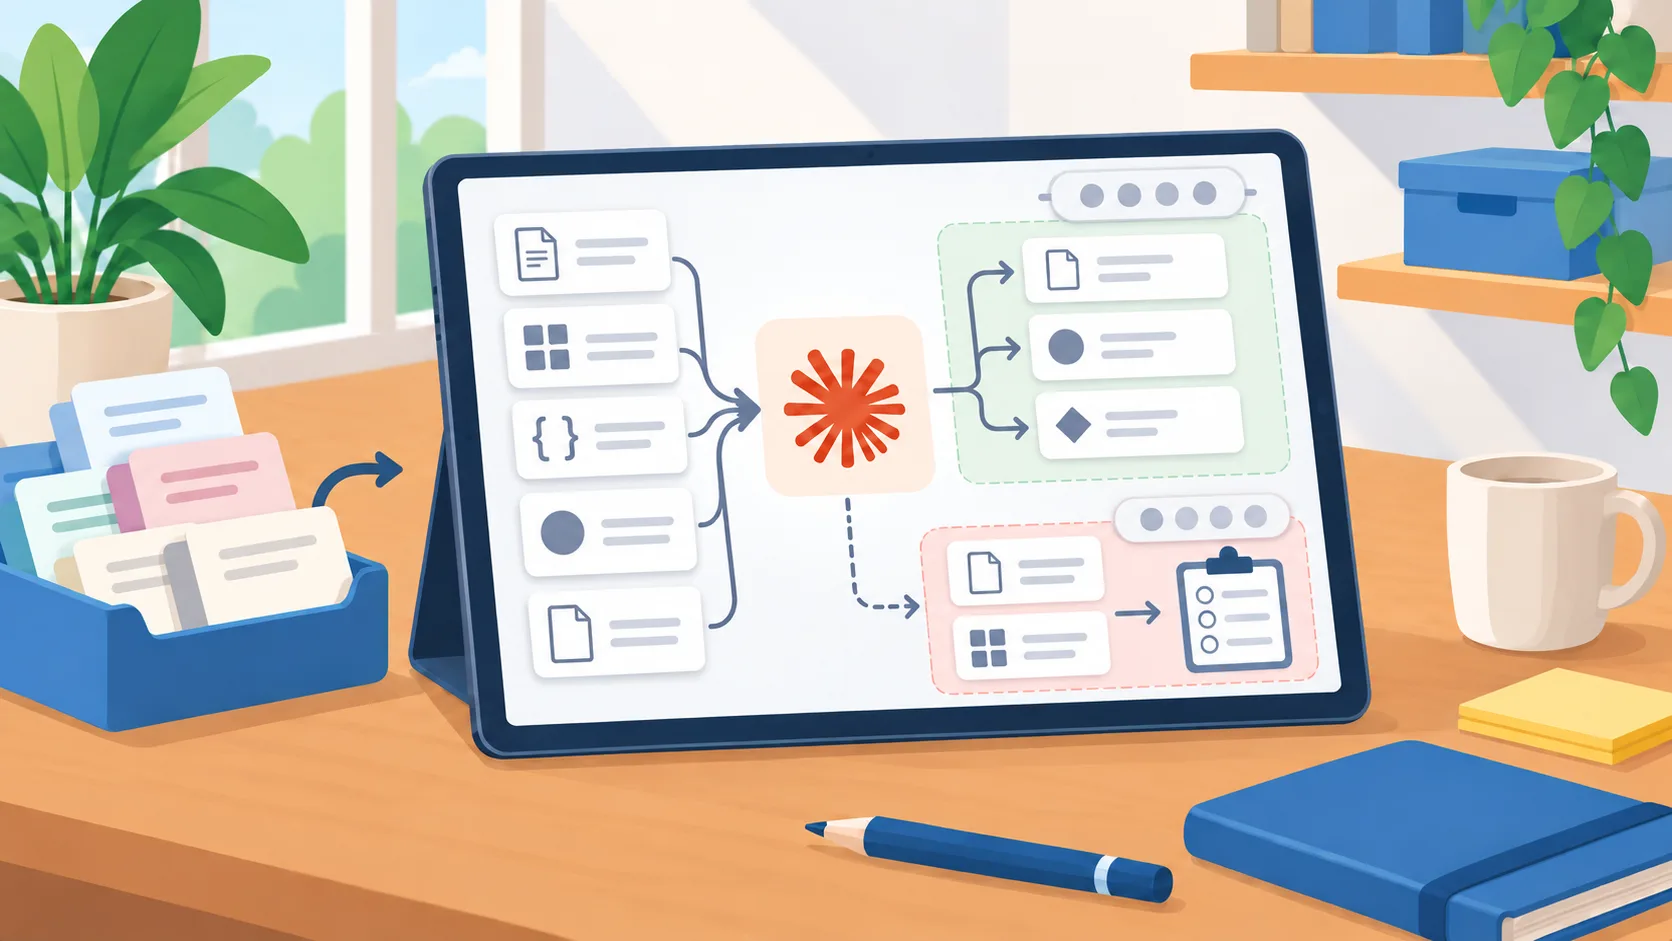
A volume task needs a plan for the cases it cannot handle. Define a confidence or quality threshold that sends uncertain work to a more capable model or a human reviewer. Keep the original input and the reason for escalation available so the fallback step does not start blind.
Make the fallback rule explicit and test it separately. Include examples where a confident but wrong answer should be caught, as well as examples where the system should refuse to guess. If a simpler model performs well on the ordinary cases but produces costly exceptions, the correct decision may be to limit its scope rather than route more work through it.
Protect the workflow from silent drift
Freeze the model identifier, prompt, output format, and tool permissions for the pilot. Keep a versioned evaluation set and rerun it when any of those change. If the task depends on an upstream form, document source changes too; a new field label can cause an extraction error that looks like model drift.
Track a small dashboard with volume, acceptance rate, correction categories, fallback count, and elapsed review time. Give each measure a definition and an owner. Do not combine dissimilar tasks into one average, because a good result on simple items can conceal failures in the narrow group that matters most.
Make the decision reversible
A safe pilot has a way to stop routing and return to the previous process. Keep the human queue open, make the reviewer’s authority clear, and preserve an audit trail of any output that can affect a customer or employee. If the team cannot reconstruct a decision or suspend the model quickly, the workflow is not ready for scale.
After the pilot, decide whether to expand, revise, or stop. Expansion should follow evidence about local quality and review burden, not a vendor ranking or another company’s use case. A clear next step is to run one task over a defined sample, review every exception, and compare the total work required with the existing process before changing production routing.