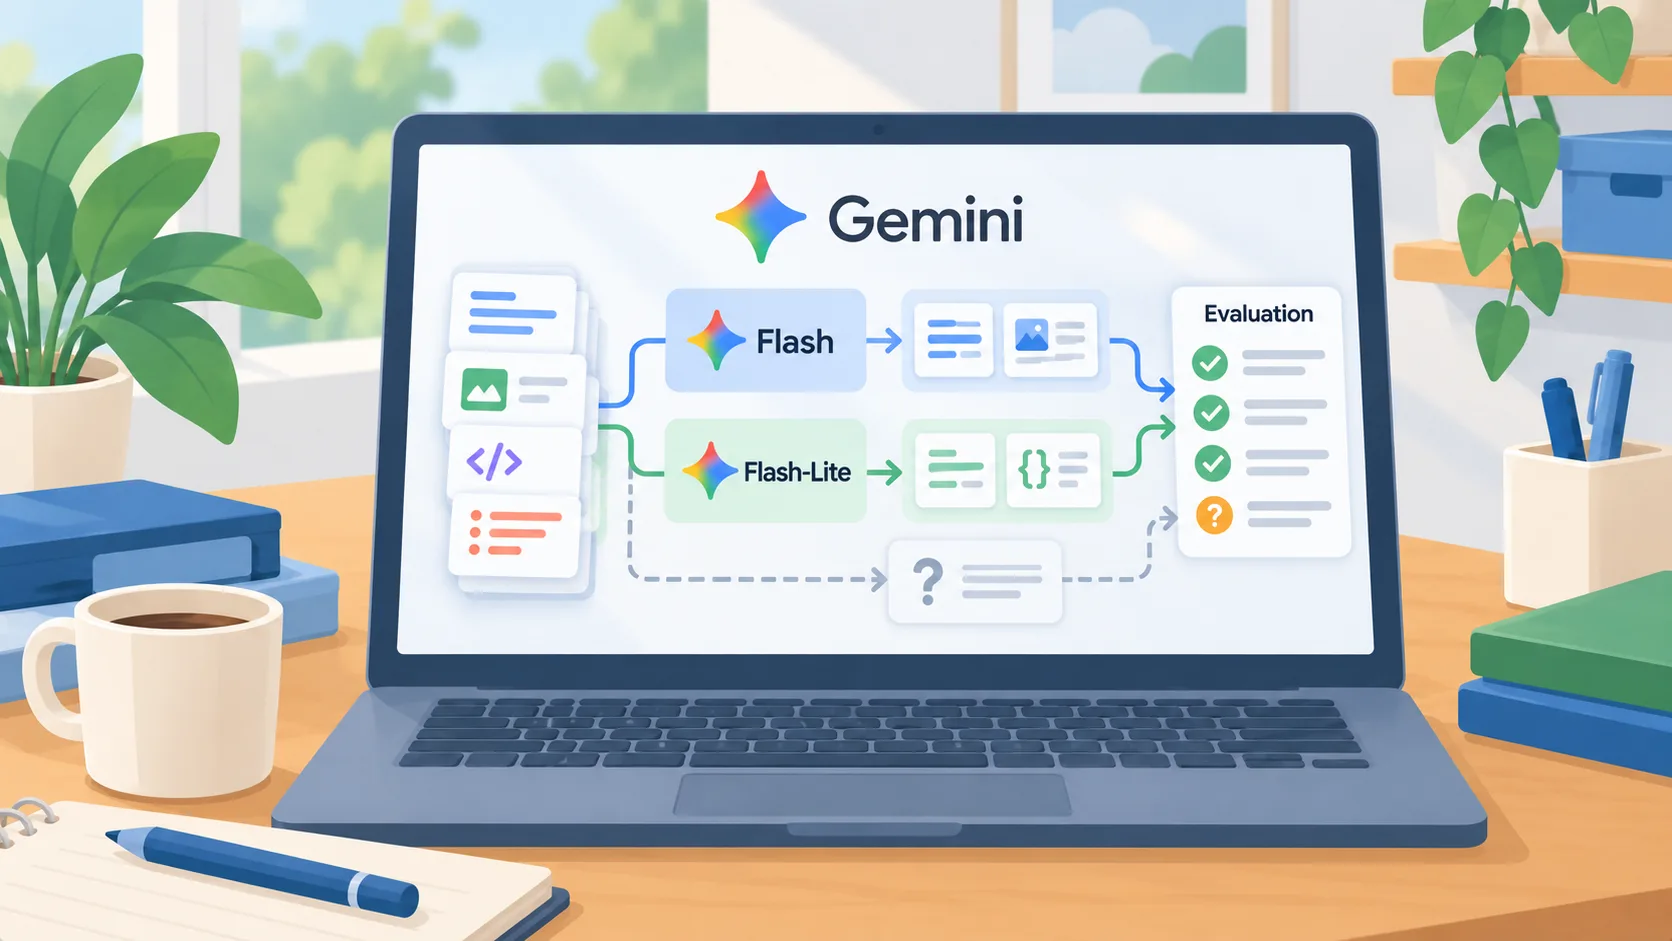
A two-tier launch is a workload decision
Google introduced Gemini 3.6 Flash and Gemini 3.5 Flash-Lite on July 21. Its announcement positions 3.6 Flash as a workhorse for coding, knowledge work, and multimodal tasks, while Flash-Lite is aimed at speed and scale. These are starting points, not a rule for every job. Test your own tasks because the acceptable balance between accuracy, response time, and review effort varies by workflow.
The announcement also includes benchmark and token-efficiency claims. Those figures are vendor-reported and depend on the benchmark and configuration. They do not tell you how either model will handle your records, terminology, edge cases, or existing instructions. Avoid translating a model family label into a guarantee such as ‘cheap enough’ or ‘good enough.’ Confirm model availability and terms in the specific API or application you use, then compare behavior under a consistent test.
Separate routine volume from costly exceptions
List the recurring AI tasks in your business and sort them by consequence if the answer is wrong. A high-volume, low-impact classification job may be a sensible candidate for a lighter model if a reviewer can quickly check uncertain cases. A task involving contract terms, customer commitments, payment instructions, or an irreversible system update needs tighter controls regardless of which model appears stronger. The cost of an error includes the time spent finding and fixing it, not just the provider’s usage charge.
Choose one workflow with repeatable inputs and a clear expected result. Gather examples that include ordinary cases, incomplete records, confusing labels, and cases where the right response is to stop or ask a human. Remove personal or confidential details unless they are necessary and properly authorized for the test. Keep the same prompt, data, and scoring rules when comparing models so the result reflects the model choice rather than a moving target.
Compare the work that reaches a human
For each model, record correctness, missing fields, invented values, and recognized exceptions. Track response time and reviewer repairs. A fast model that triggers frequent correction may increase total work. A stronger model might handle only cases the first pass marks uncertain, but test that routing rather than assuming it works.
Include operational costs in the comparison: integration effort, monitoring, fallback behavior, and the time needed to explain the result to an employee. Avoid building a complicated router until a simple sample shows where the tiers differ. If results are close, pick the option that fits your existing environment and is easiest to maintain. The more important decision may be how the system handles uncertainty, not which model wins an average score.
Decide where a smaller model is allowed to act
A lower-cost or faster model can be useful for drafting, sorting, and extracting candidate values when the business keeps a verification step. It should not gain extra permission just because it is inexpensive. Restrict the tools and data each workflow needs, and keep consequential changes behind an approval point. When a model cannot meet the required quality on a defined case, the workflow should route to a capable reviewer or fail safely rather than quietly accepting a weak answer.
Write down the acceptance threshold before testing. Define the errors that disqualify a model, the exception rate that is manageable, and who owns the decision to change providers. Re-run the examples when the prompt, model version, source data, or integration changes. This makes the decision durable enough to revisit when the catalog changes without treating the original test as a permanent endorsement.
Run a small comparison before choosing a default
Take a few dozen representative, sanitized tasks and compare both models under the same conditions. Ask the workflow owner to review the outputs without being told which model produced each one when practical. Summarize both the misses and the human correction work. If a distinction appears, route only the task types where evidence supports it. If there is no meaningful operational difference, avoid extra complexity and select based on the verified deployment requirements.
Google’s July release expands the available choices; it does not make model selection automatic. Business owners can turn that choice into a focused test, set permission boundaries, and make the model earn its place in the workflow.